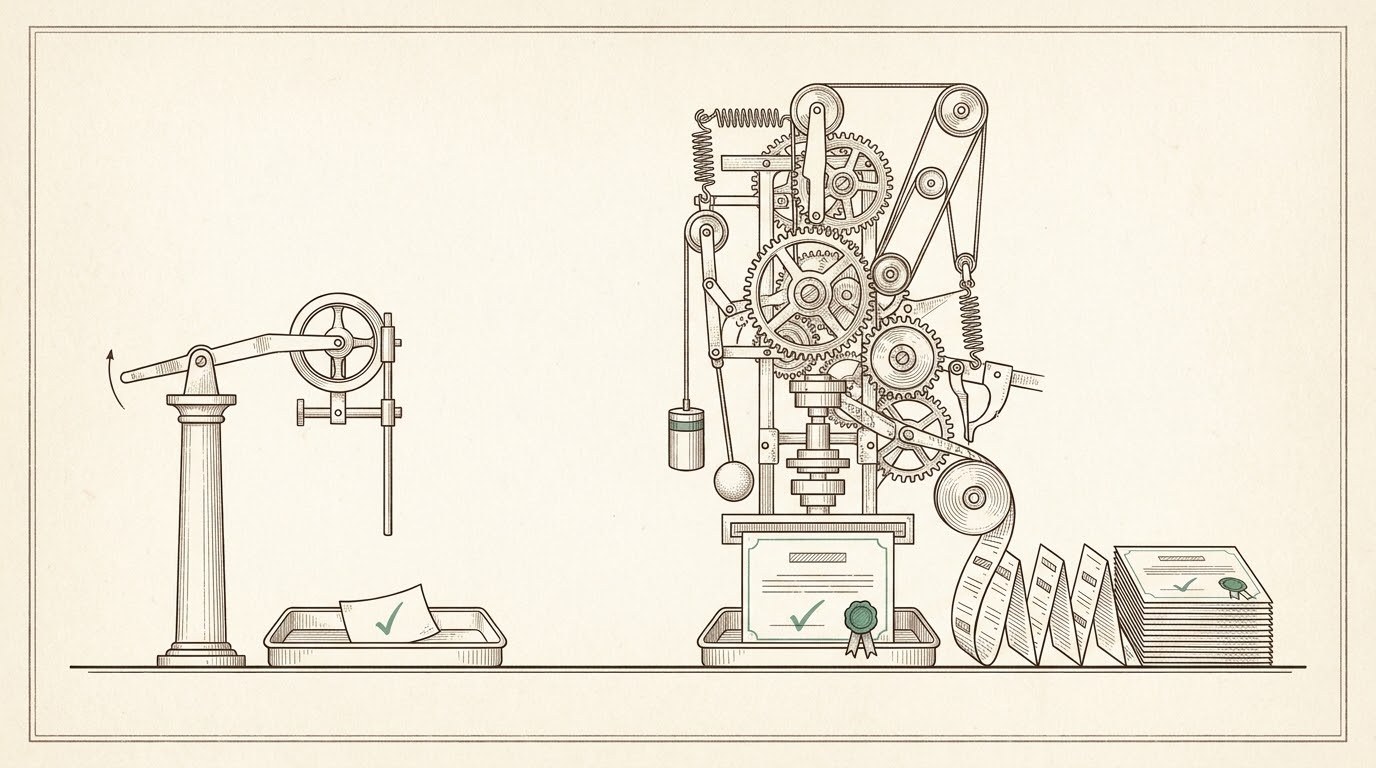
Measuring my agent harness against plain Claude Code
I built a multi-agent harness and ran it head to head against a plain control on a real benchmark. On these tasks it cost about five times more and did not score better. What it bu...
I built a multi-agent harness and ran it head to head against a plain control on a real benchmark. On these tasks it cost about five times more and did not score better. What it bu...
The AI Art Magazine is running an open call where agents submit the work and agents judge it. I registered one and let it choose. It didn't choose the piece I wanted, or the one it...
I've been running my context-management discipline on a real client programme where most of the execution is done by agents. The principles held up. The rules that were only writte...
A new piece lays out the mechanisms behind context rot and gives concrete token thresholds. I have been hitting those thresholds by hand since February. This post covers where the...
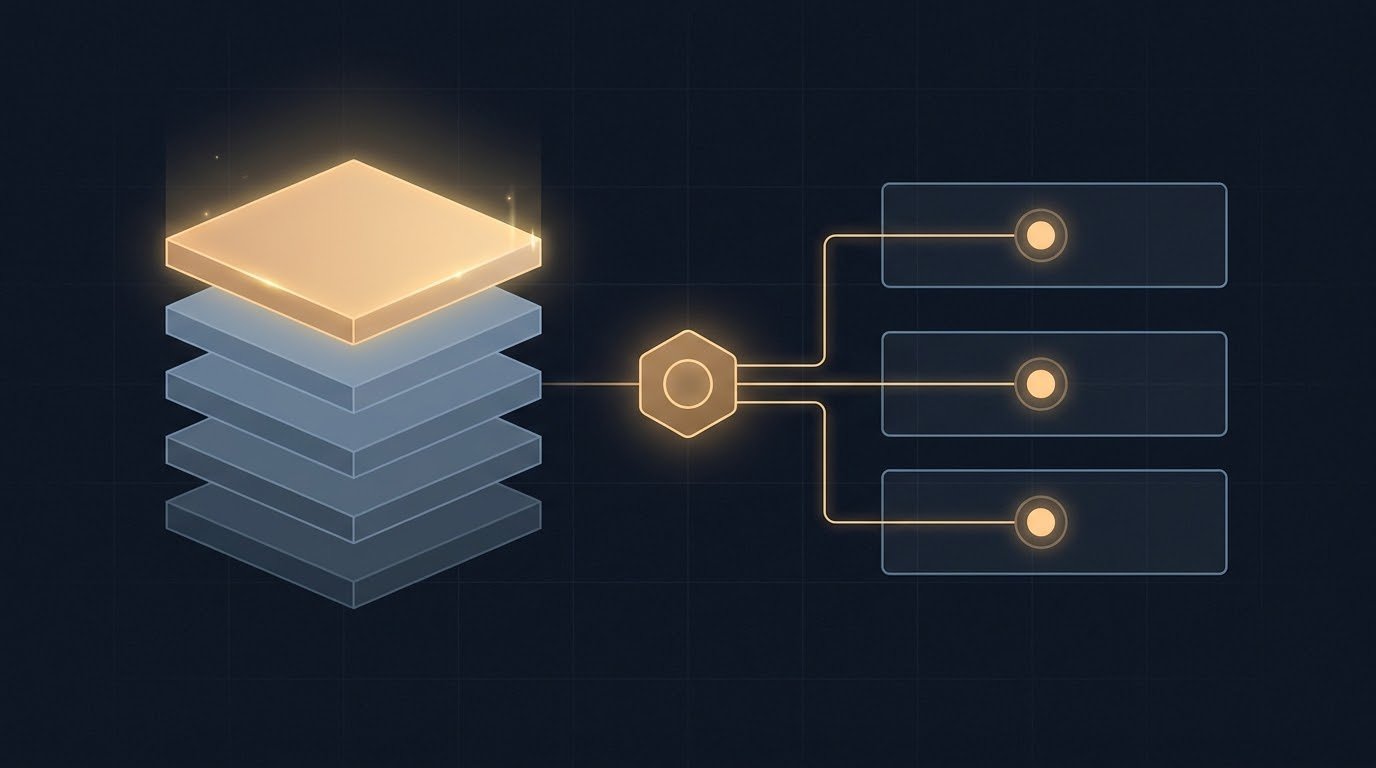
Anthropic launched Claude Fable 5 yesterday, its first Mythos-class model, priced at double Opus. The context window did not grow. What changed is the management layer around it.
I've been experimenting with feeding agents larger volumes of context. The pattern is steady: the bigger I make it, the worse it looks. Meanwhile, the rest of the field is racing t...

I've spent months building context management patterns by hand. Here's how the four major platforms are solving the same problems at the infrastructure level, and what it means for...
I've been writing about context management at the individual and team level. This post zooms out: if context is the real bottleneck in AI, who owns it across an organization, and w...
We've been solving the 'too complex for one person' problem for decades in program delivery. Now some team members are language models, and the coordination overhead is measured in...
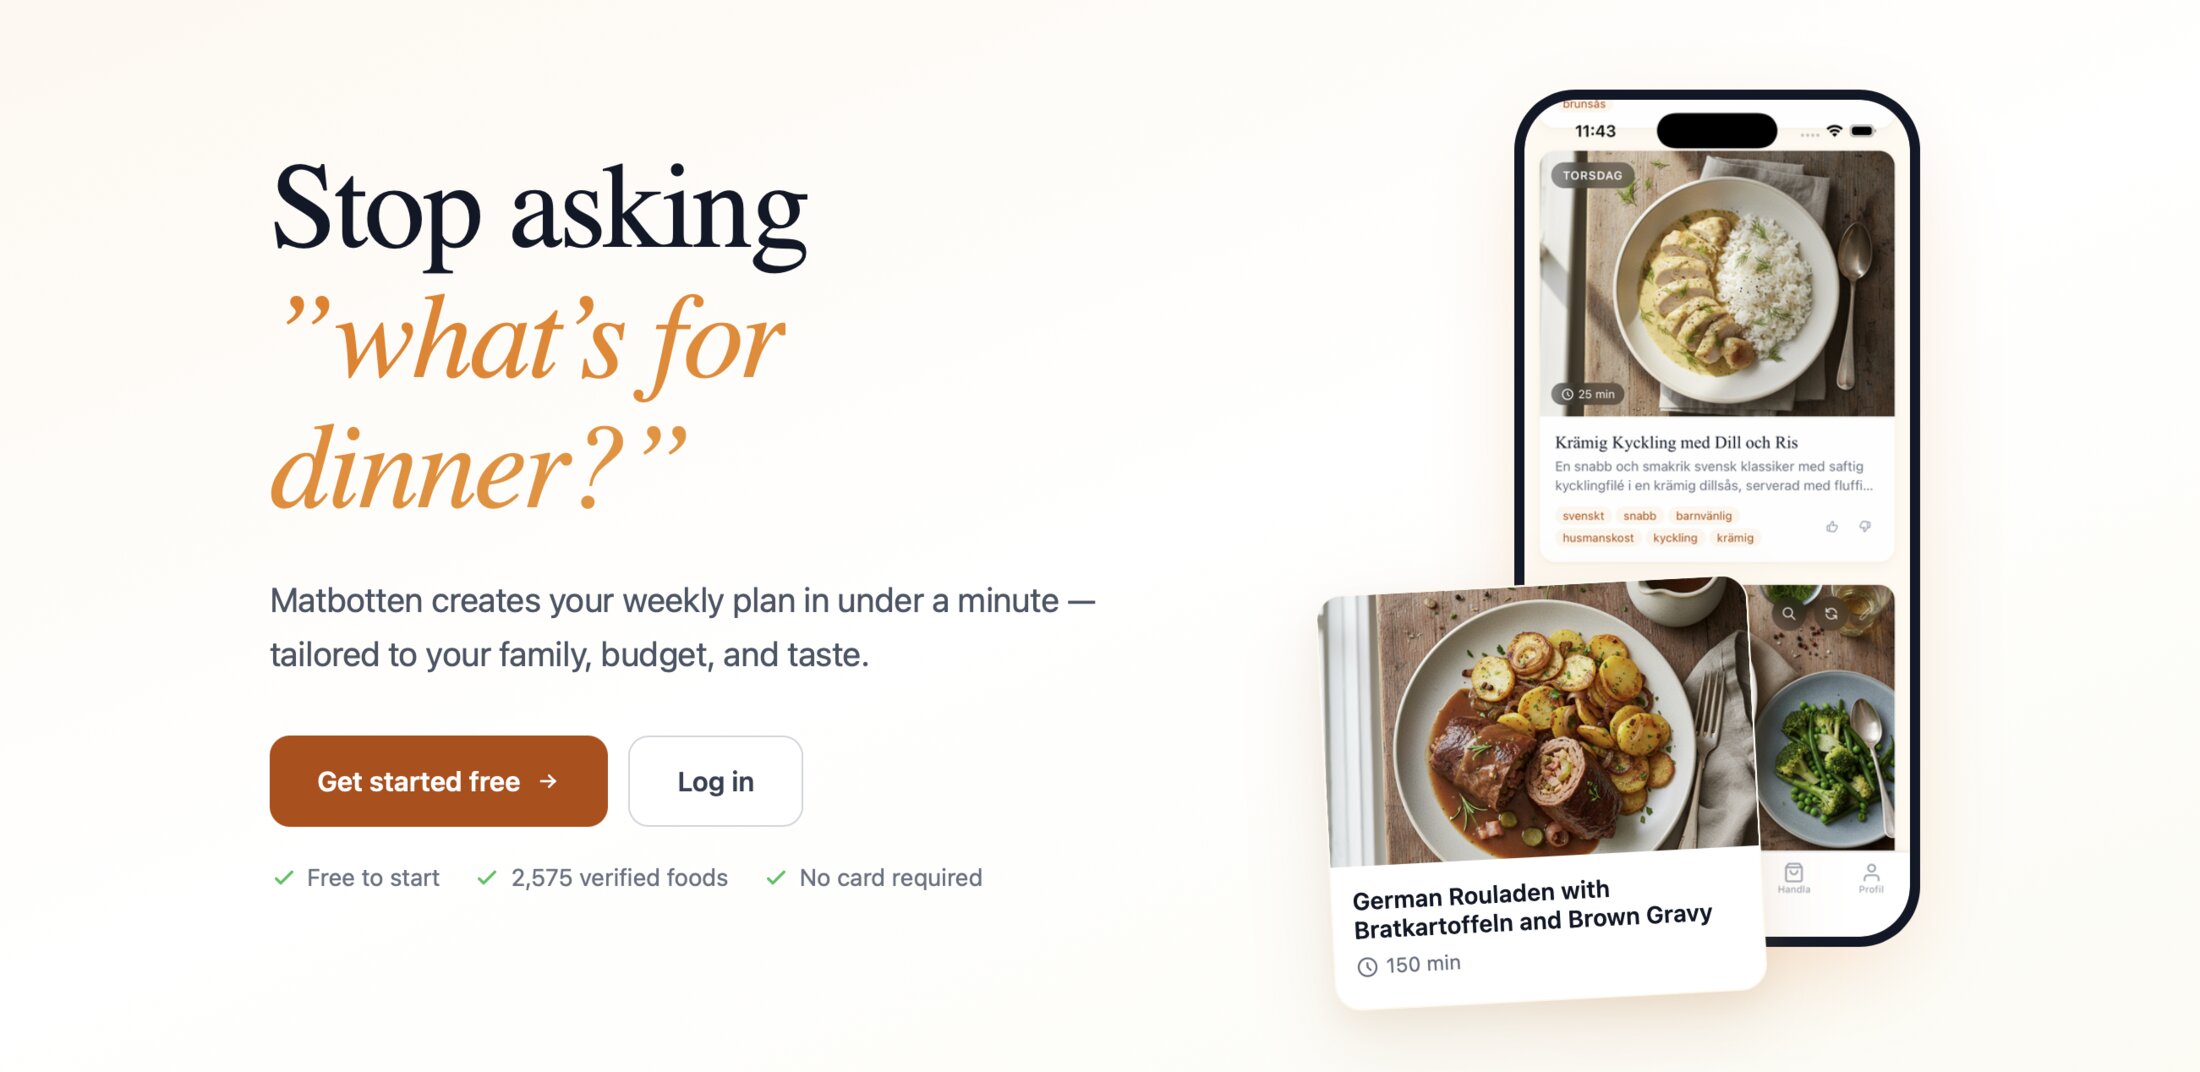
Six years ago I helped a CPG company design a smart meal planner. We never shipped it. This year my wife and I built it, and we use it every week.